
Local runtimes
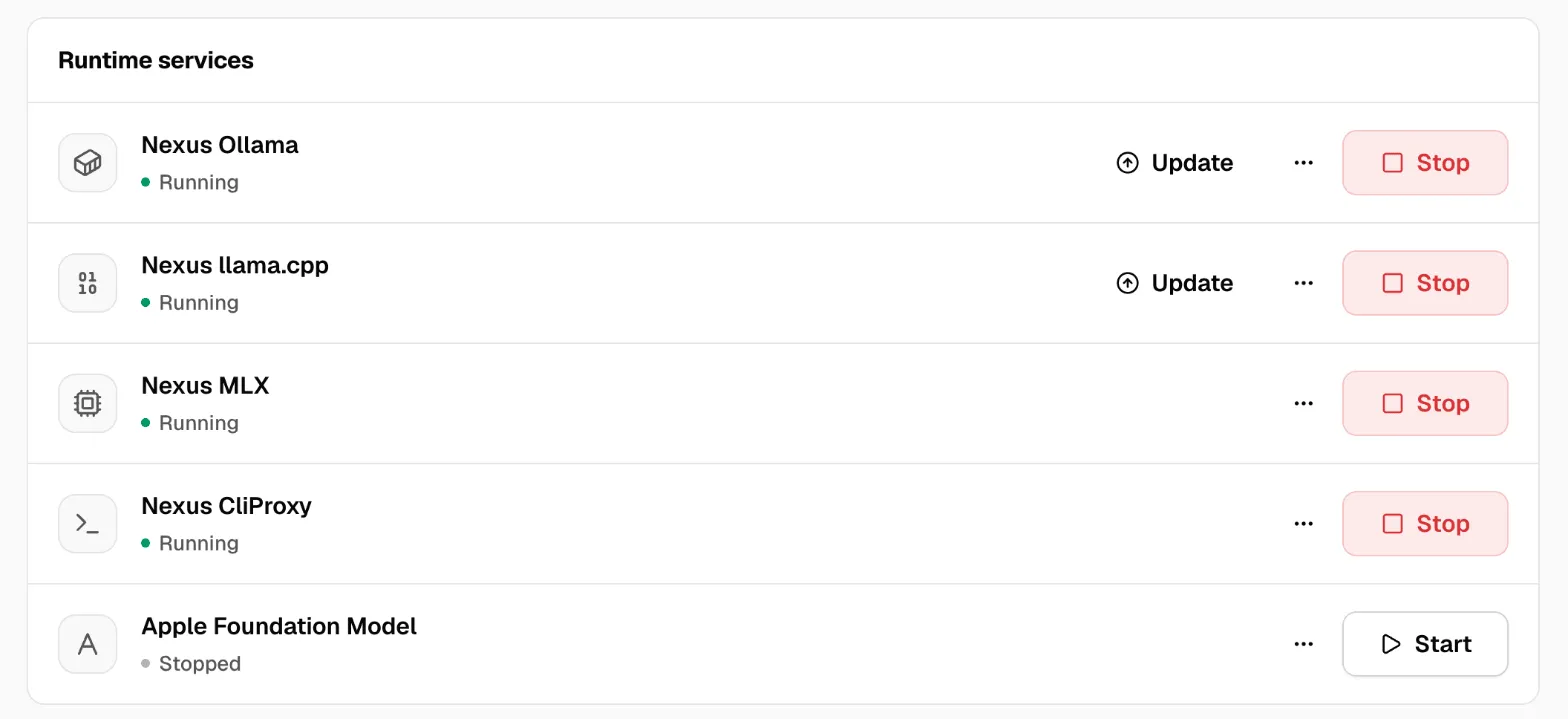
A local runtime is the engine that runs models on your own machine. Nexus can install it, start it, keep it updated and tune it, so your apps only ever talk to Nexus.
Local runtimes are on Providers → Local runtimes. Their settings are on Settings → Local runtimes.
Which runtime does what
Section titled “Which runtime does what”| Runtime | Runs | Where |
|---|---|---|
| Nexus llama.cpp | GGUF model files, from Hugging Face or your disk. | macOS, Windows, Linux |
| Nexus MLX | MLX models, built for Apple silicon. Usually the fastest choice on a Mac. | macOS on Apple silicon |
| Nexus Ollama | Models from the Ollama library, including embeddings. | macOS, Windows, Linux |
| Apple Foundation Model | The model built into macOS. Text only. Nothing to download. | macOS 26 or later, on Apple silicon with Apple Intelligence |
| Nexus CliProxy | Your Claude, ChatGPT (Codex) and Antigravity subscriptions. See Connect a subscription. | macOS, Windows, Linux |
You don’t need all of them. Start with one: MLX on a Mac, llama.cpp elsewhere.
Install and start
Section titled “Install and start”- Open Providers → Local runtimes.
- On the runtime’s card, click Install. Nexus downloads it and checks it before it runs.
- Click Start.
Each action runs as a job. You can leave the page; follow it in Activity.
You often don’t need this step. When you download a model in Models, Nexus installs and starts the runtime it needs first.
Other actions on the card: Stop, Restart, Update, Roll back to the previous version, Uninstall, and Disable. Discover existing models adds models the runtime already has.
Runtimes Nexus didn’t install
Section titled “Runtimes Nexus didn’t install”A card shows who owns the runtime:
- Managed by Nexus: Nexus installed it and can start, stop, update and remove it.
- External runtime: you started it yourself, such as your own Ollama. Nexus uses its models but won’t stop or remove it.
Port in use means another program already uses the runtime’s port. Usually that’s a copy you started yourself. Stop it, then click Start here, if you want Nexus to manage it.
Uninstall removes only what Nexus installed. It keeps your downloaded models and your model list, and never touches a runtime you installed yourself.
Updates
Section titled “Updates”Nexus checks runtimes for updates and shows Update available on the card. Click Check for updates to check now.
- Click Stop. A running runtime can’t be updated.
- Click Update to the new version.
- Click Start.
If the new version gives you trouble, click Roll back.
Nexus installs only runtime software it can verify. Your organization may set where updates come from, or turn them off. Apps that call Nexus can’t change this.
Tune a runtime
Section titled “Tune a runtime”- Open Settings → Local runtimes.
- Pick the Runtime.
- Change what you need under Tuning.
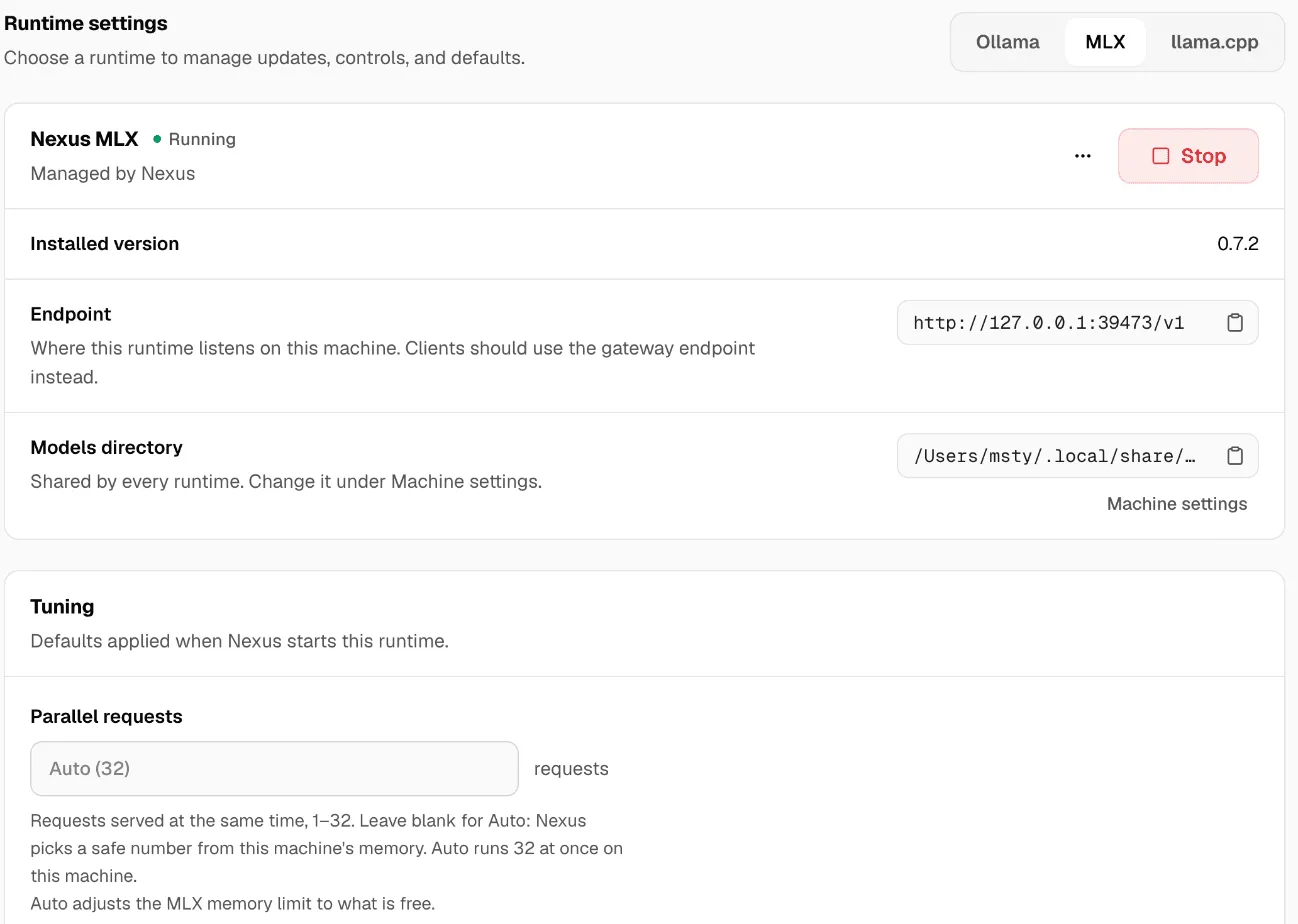
Leave a field blank, or pick Auto, and Nexus or the runtime decides. Most machines need no changes. Changes apply the next time Nexus starts the runtime.
| Setting | What it changes |
|---|---|
| Parallel requests | How many requests run at once. Auto picks a safe number for this machine’s memory. |
| Context length | Tokens of context for each request. For llama.cpp, it’s shared across parallel requests. |
| Maximum loaded models | How many models stay loaded. More answer faster but use more memory. |
| Keep alive | How long an idle model stays loaded. |
| Maximum queue | How many requests may wait when every slot is busy. |
| KV cache quantization (MLX) | Shrinks the conversation cache. 8-bit is nearly lossless; 4-bit halves it again. |
Advanced holds power settings, such as flash attention, KV cache type, GPU layers, threads and batch sizes. The defaults suit most machines.
Turn off model thinking helps when an app can’t show a model’s reasoning and seems to hang while it streams.
When every slot is busy
Section titled “When every slot is busy”Busy models applies to every local runtime. When all slots are taken, requests wait in line. Longest expected wait sets a limit, from 10 to 600 seconds. If a request would wait longer, Nexus answers “busy, try again shortly” at once, instead of leaving the app hanging.
Acceleration engine
Section titled “Acceleration engine”On machines with more than one way to use the GPU, Acceleration engine picks which one llama.cpp uses. Automatic picks the best tested engine for this computer. Only engines ready on this machine are listed.
Where models are stored
Section titled “Where models are stored”All runtimes share one Models directory, inside their own folders. Change it on Settings → Machine → Storage.
If something goes wrong
Section titled “If something goes wrong”| What you see | What to do |
|---|---|
| Not installed | Click Install. |
| Port in use | Stop the other copy of the runtime, then click Start. |
| Update (Stop the runtime to update) | Click Stop, then update. |
| A runtime isn’t listed | It doesn’t run on this machine’s system. MLX and Apple Foundation Model need a Mac with Apple silicon. |
| An action failed | Click View failed job to see why. |
| The runtime fails to start | Check the job in Activity, and Diagnostic logs there. |