
Models
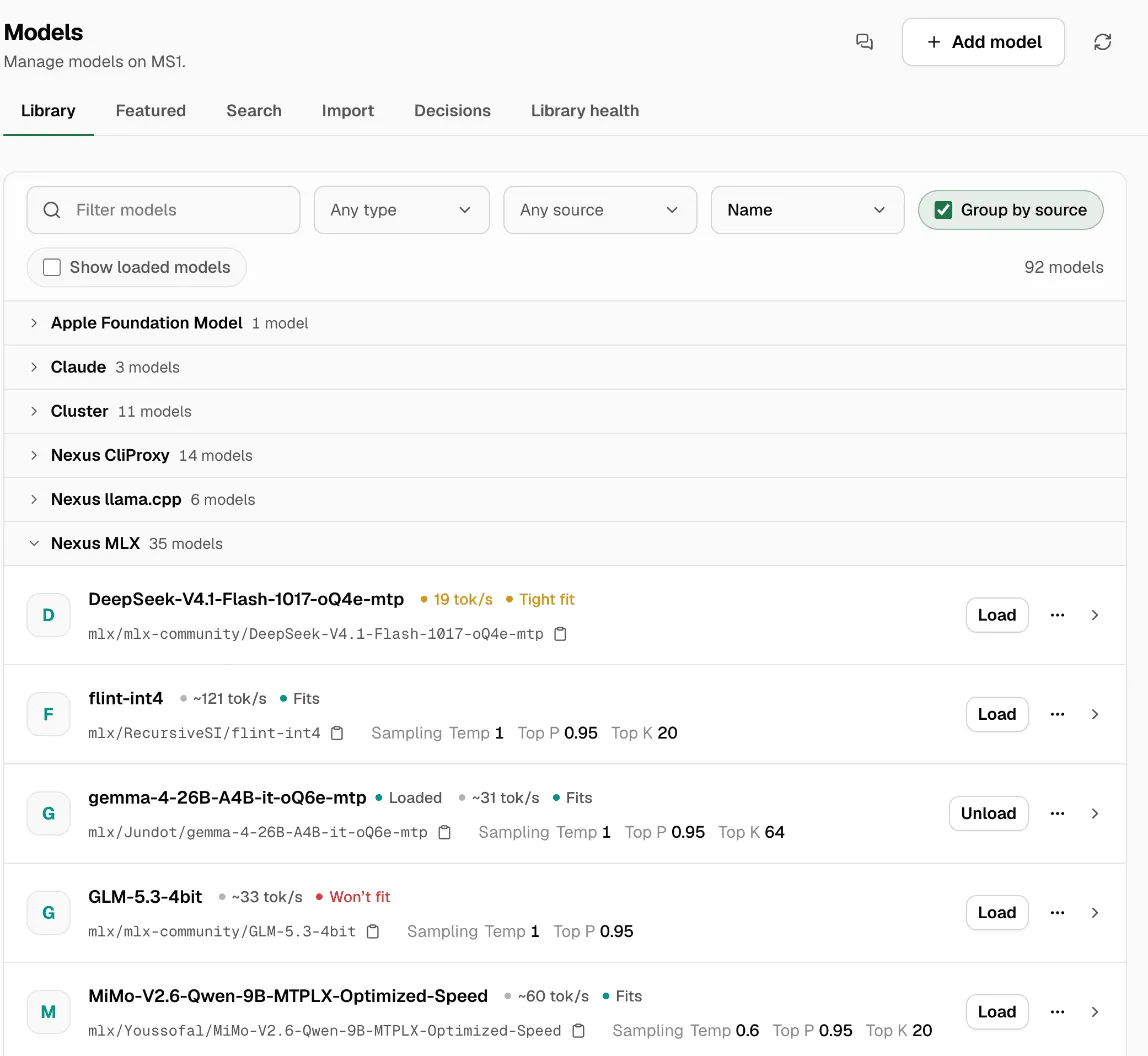
Models lists every model this machine can serve: models you downloaded, models from your providers, and models other apps on this machine already have. Apps call a model by its ID, such as mlx/qwen3-8b or openai/gpt-5.
The page has these tabs:
| Tab | What it’s for |
|---|---|
| Library | Every model on this machine. Load, hide, copy and tune them. |
| Featured | Models we picked that run well, with a fit check for this machine. |
| Search | Find models on Hugging Face and the Ollama library. |
| Import | Use models other apps already downloaded, or a GGUF file on disk. |
| Decisions | Set up models that answer yes/no, choose-one and score questions. |
| Library health | Find missing, broken and unused model files. |
Download a model
Section titled “Download a model”- Open Models → Featured to pick from tested models, or Search to find any model.
- Check the fit badge: Fits, Tight fit or Won’t fit. It compares the model’s size with this machine’s memory.
- Click to download.
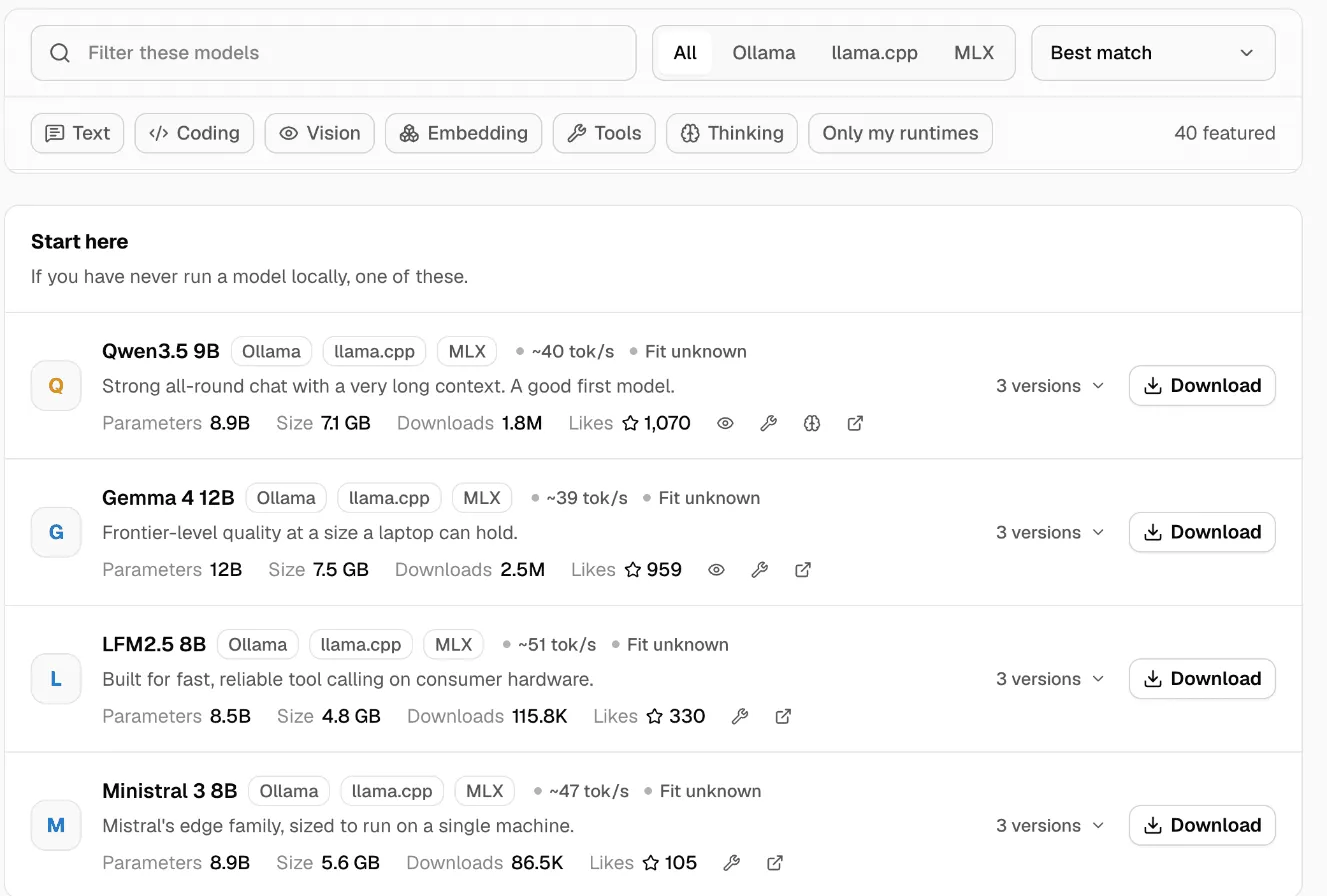
Nexus picks the runtime: MLX for MLX models on a Mac, llama.cpp for GGUF files, Ollama for Ollama models. If that runtime isn’t installed or running, Nexus sets it up first and then carries on with the download.
Downloads wait in a queue and keep going after a restart. Nexus checks each file when it arrives. Follow the progress in Activity.
If one source, such as Hugging Face, is down, search still shows results from the others and says which one failed.
Use models other apps downloaded
Section titled “Use models other apps downloaded”Already have models from Msty Studio, LM Studio or Ollama? Link them instead of downloading them again.
- Open Models → Import.
- Under From other apps on this machine, wait while Nexus looks through those apps’ folders.
- Tick the models you want and click Link selected.
Linked models stay where they are. Nexus doesn’t move, copy or delete them. Unlink selected removes only the link.
If MLX must restart to use the new models, Nexus asks: Restart MLX to use linked models? A restart unloads MLX models and stops their open chats, so pick Later if people are using them.
Nexus skips files that are incomplete, unreadable or already linked, and tells you which.
Import a GGUF file
Section titled “Import a GGUF file”- Open Models → Import.
- Under Import a local GGUF, enter the Model file name and the Path on this machine.
- Click Start import.
The path is on the machine running Nexus, which may not be the computer you’re using. Nexus copies the file into its own models folder. This needs llama.cpp; if it isn’t ready, click Set up llama.cpp.
Load, hide and find models
Section titled “Load, hide and find models”In Library, for each model:
- Load puts a local model in memory so the first reply is fast. Unload frees the memory. Show loaded models lists only what’s in memory now.
- Visible and Hidden control whether apps can see the model. A hidden model isn’t in the model list, can’t be called by ID or alias, and doesn’t show in Smart Route and preset pickers.
- Try in Chat Lab opens it in Chat Lab.
- Copy model id copies the name apps send.
- Create Smart Preset… makes a preset with good settings for this model.
For a stable name that won’t change when you swap the model, use a model alias.
See how a model performs
Section titled “See how a model performs”Open a local model’s Performance… to see how it does on this machine.
- Speed: tokens per second, and how speed drops as prompts get longer.
- Memory: how much memory it uses, and how much conversation fits.
- Accuracy: how this version scores against other versions of the same model.
- How long things take: expected time for a short answer, a long answer, an agent turn or a document.
- In your apps: how long the prompts your apps really send are.
- What it can do: tools, structured output, images and long context. Nexus tests these once, the next time the model loads while the machine is idle.
- Versions: compare quantizations of the same model side by side.
Each number says where it came from: Tested … on your hardware, tested on a similar chip, or an Estimate. Treat estimates and small samples as a guide. For your own workload, run a benchmark.
Compare Macs shows how the model runs on other Apple silicon chips, from community measurements and benchmarks that Nexus users chose to share.
Slower here appears when this machine is often slower than similar machines. Check memory pressure, other loaded models, Low Power Mode and heat before you change the model.
Hardware and memory
Section titled “Hardware and memory”Under Hardware, Nexus works out which GPUs and how much memory hold the model.
- Click Work out a setup.
- Review the proposal.
- Click Apply. Nothing changes until you do.
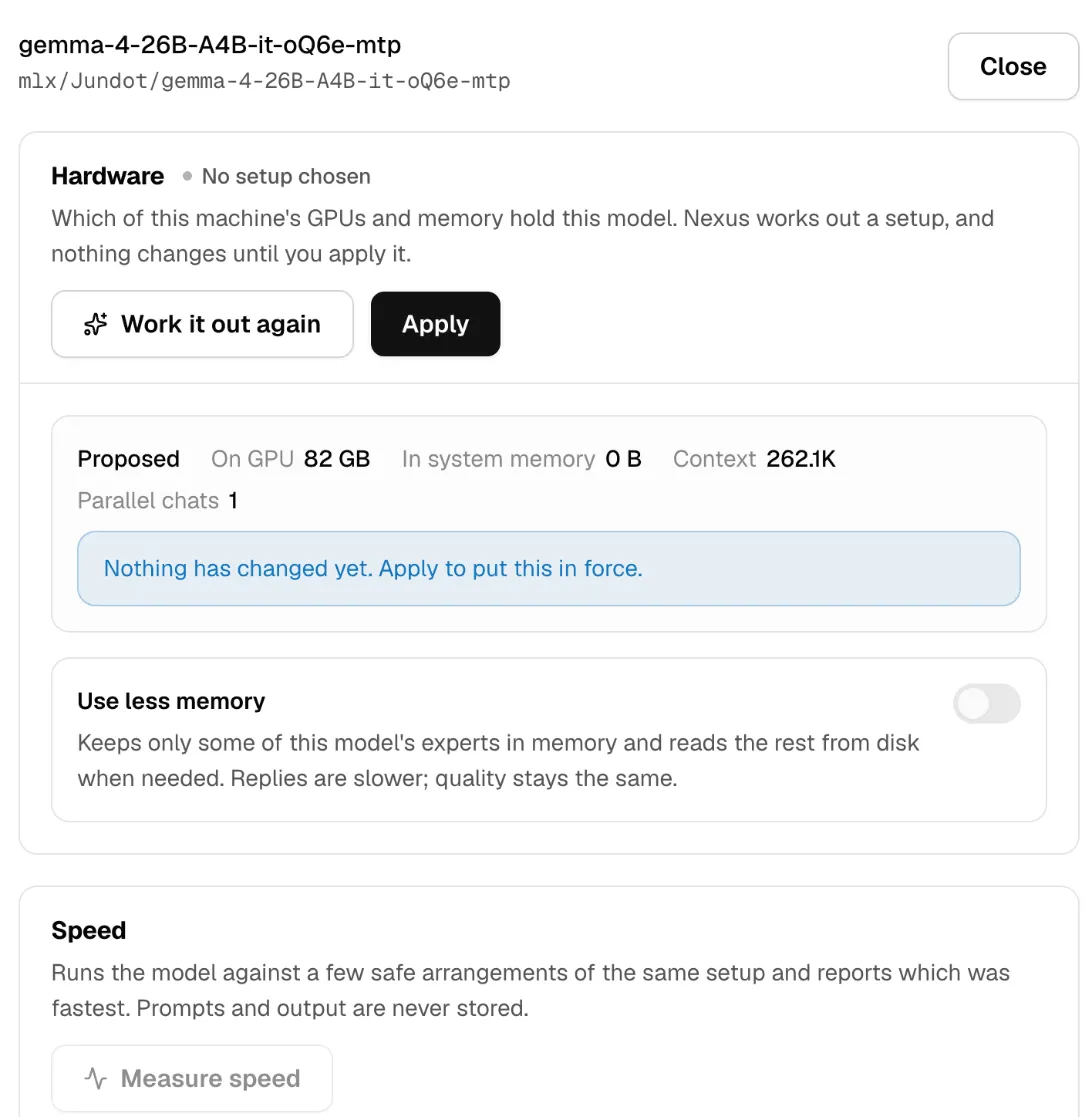
Measure speed tries a few safe setups and tells you which was fastest. Prompts and output are never stored.
Use less memory suits some large mixture-of-experts models. It keeps only part of the model’s experts in memory and reads the rest from disk. Set Experts kept in memory from 5 to 100 percent. Lower saves more memory but replies slower. Answer quality stays the same.
Copy a model to another machine
Section titled “Copy a model to another machine”This needs a second machine in your fleet, so Pro or Enterprise.
If one of your machines already has a large model, copy it instead of downloading it again.
- In Library, open the model’s menu and click Copy to….
- Pick the machine. Nexus shows the size, and whether it must install a runtime first.
- Click Continue.
Keep both machines on until the copy finishes. The other machine checks the whole model before it uses it. slower, over VPN means the machines can’t reach each other directly, so the copy takes a longer path.
Copying a model doesn’t give anyone access to it. Team policy, hidden models and key limits still apply on the other machine.
Decision models
Section titled “Decision models”Decision models answer questions with a choice and a probability, not with prose. They power Decision presets and Describe it in the preset creator.
- Open Models → Decisions.
- Nexus recommends a model that fits this machine. Click Set up.
- Wait for it to download. The download continues if you leave the page.
- Click Make default.
No local model fits? Connect TypeSafe AI or OpenRouter in Providers to use hosted decision models.
Try and compare asks up to three decision models the same question, so you can compare them.
Library health
Section titled “Library health”Library health checks model files against what each runtime and Nexus expect. It finds:
- Files that are missing, or the wrong size
- Unused files that take up space
- Models a runtime has that Nexus doesn’t list, and the other way round
Each problem comes with a fix, such as Download again or Delete file. Remove cleans up unused files after you confirm. Nexus keeps any file it isn’t sure about.
Run it after you change models outside Nexus, or after a download was cut off.
For developers: what a model can do
Section titled “For developers: what a model can do”Each model in GET /v1/models lists the API families it supports, such as chat completions, Responses, embeddings or Anthropic Messages. Nexus refuses a request to a model that doesn’t support that API, before it reaches the provider.
Models can also carry msty_capabilities, such as tool use, vision and context length. A null value means Nexus doesn’t know, not that the model can’t. See the Gateway reference.
If something goes wrong
Section titled “If something goes wrong”| What you see | What to do |
|---|---|
| Won’t fit | Pick a smaller version, or try Use less memory if the model offers it. |
| Search is unavailable | One source is down. Try again later, or use another tab. |
| A download stopped | Check Activity. Downloads pick up again after a restart. |
| A model is missing | Check it isn’t Hidden, and run Library health. |
| Delete fails because the model is in use | Change the presets, aliases or Smart Routes that use it first. |
| Slower here | Unload other models, plug in the Mac, and check Low Power Mode. |